
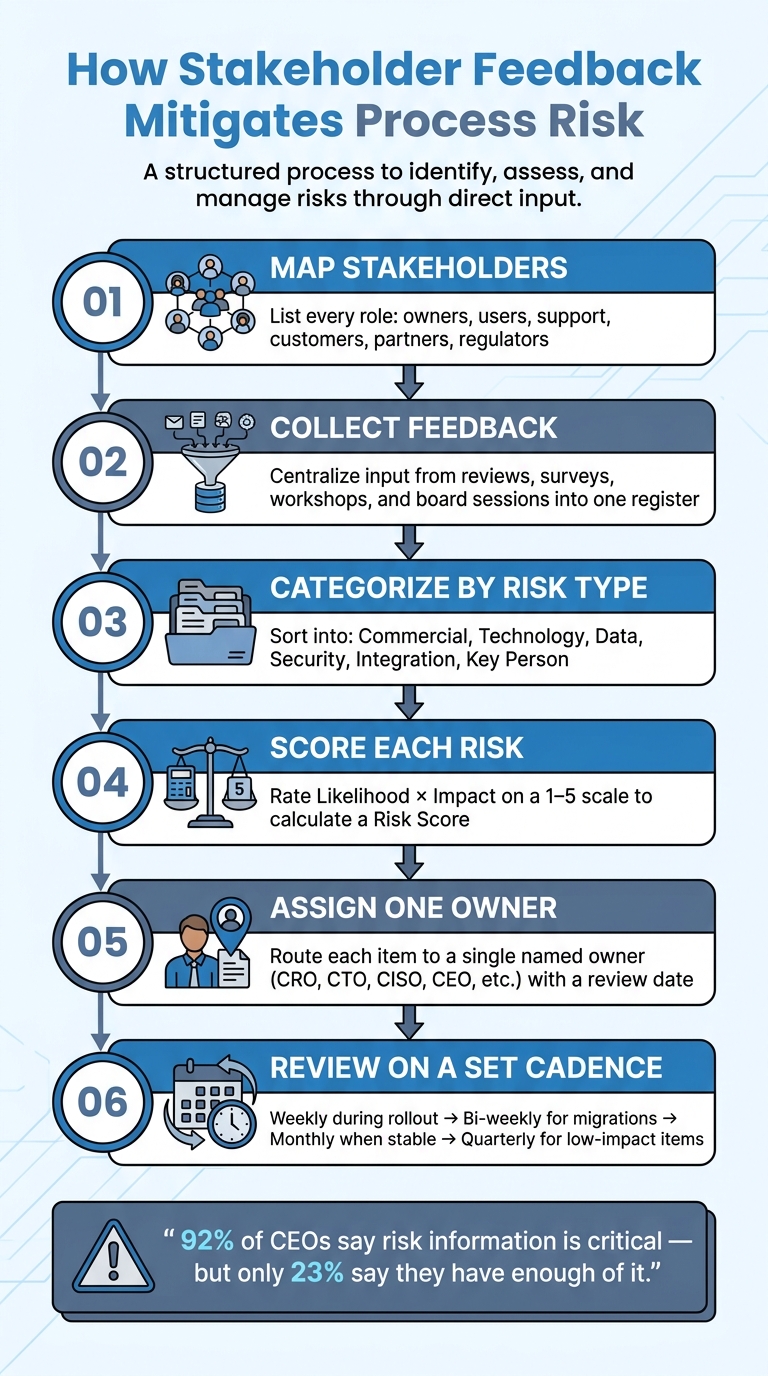
Most process failures start as small warnings that no one logs. If you want to cut process risk, I’d do six things early: map stakeholders, collect feedback in one place, sort each issue by risk type, score it, assign one owner, and review it on a set schedule.
Here’s the short version: when feedback stays in emails, meetings, and side chats, teams miss risk until it turns into delays, data mistakes, system issues, or rework that costs time and money. And that gap is common – 92% of CEOs say risk information matters, but only 23% say they have enough of it.
If I were setting this up, I’d keep it simple:
- List every group tied to the process: owners, users, support, customers, partners, and regulators
- Turn comments into risk items instead of leaving them as loose notes
- Sort each item into commercial, technology, data, security, integration, or key-person risk
- Score likelihood and impact on a 1–5 scale
- Send each item to one owner with a review date
- Track decisions and follow-up so fixes don’t disappear after the meeting
A few points matter most:
- Unstructured feedback creates blind spots
- Frontline staff often spot risk first
- One register works better than scattered docs
- One owner per item avoids confusion
- Re-scoring risk after follow-up shows whether the fix worked
If you compare the two approaches, the difference is pretty plain:
| Area | Ad hoc handling | Risk-based handling |
|---|---|---|
| Visibility | Scattered across chats and notes | Logged in one register |
| Response | After damage shows up | Before issues get worse |
| Ownership | Unclear | One named owner |
| Follow-up | Easy to lose | Reviewed on a set cadence |
I see the article’s main point as simple: feedback is not just input – it is an early risk signal. When you treat it that way, process change gets easier to control and less likely to drift.
How to Turn Stakeholder Feedback into Process Risk Control
Map stakeholders and convert feedback into risk items
Identify the stakeholder groups tied to the process
Start by listing every role that touches the changed process: owners, approvers, users, support teams, customers, partners, and regulators. Each group tends to spot a different kind of failure, so your map should show both role and department.
A RACI map helps here. It shows who is responsible, accountable, consulted, and informed. When you map stakeholders by role and department, communication gaps are much easier to catch before they turn into bigger problems.
The point isn’t to name every single person involved. It’s to spot the people who can flag risk early and the people who can do something about it.
Sort feedback by risk type, impact, and urgency
After you’ve mapped stakeholders, turn their comments into risk items. A complaint like "slow approvals" or "confusing handoffs" tells you something is off, but by itself, it doesn’t give you a clear next step.
Instead, translate each comment into a risk item and place it into one of six categories:
- Commercial: lost revenue from the new process
- Technology: technical debt, system failures
- Data: compliance gaps
- Security: access controls
- Integration: process harmonization delays
- Key Person: institutional knowledge lost during the change
Then score each item on a 1–5 scale for both Likelihood and Impact. Multiply those two numbers to get a Risk Score. From there, use score thresholds to decide when mitigation should start and when escalation is needed.
Each item should go into a register with the category, likelihood, impact, owner, and mitigation status. That way, feedback stops being a loose comment and becomes something you can track.
Ad hoc feedback handling vs. risk-based categorization
Ad hoc feedback usually goes nowhere. No owner. No tracker. No follow-up. That’s the whole problem.
Here’s what changes when feedback is handled through risk-based categorization:
| Feature | Ad Hoc Feedback | Risk-Based Categorization |
|---|---|---|
| Visibility | Siloed; often hidden until a failure occurs | Centralized in a living risk register |
| Speed of Response | Reactionary; occurs after the damage is done | Proactive; mitigation starts before the risk materializes |
| Accountability | Vague; no clear owner | Named owner with tracked mitigation status |
Structured intake helps prevent missed ownership and slow action. Once risks are mapped, the next move is a standard intake process that sends each item to the right owner.
sbb-itb-c53a83b
Build a structured feedback intake process
Set standard intake channels and required fields
After classification, the next control is intake. Every risk item should enter the system through the same path.
Use one intake method so each issue is logged in the same way. Keep the channel set tight: review cycles, customer surveys, workshops, and board reviews. Then feed everything into one risk register, not loose notes spread across docs, inboxes, and meeting decks.
Each field helps with triage, ownership, or escalation:
| Field | Purpose |
|---|---|
| Process step affected | Pinpoints where in the workflow the issue lives |
| Stakeholder role | Identifies who flagged it and their distance from the issue |
| Issue observed | Describes what is actually happening |
| Business consequence | Shows the operational or financial impact |
| Owner | Names the single team responsible for action |
You can also include optional fields like suggested fix and date submitted.
The business consequence field matters a lot. It turns a vague complaint into something the team can assess as a measurable risk. Without it, feedback stays fuzzy. With it, you can judge impact, sort urgency, and decide what needs attention first.
Route feedback to the right owner without bottlenecks
Feedback should move straight to the team that can cut the risk.
Standard fields make items easy to compare. Routing rules make them usable. Assign each item to the single team that can act first. Commercial issues go to the CRO. Technology issues go to the CTO. Security concerns go to the CISO. Integration issues go to the project lead. Key person risks go to the CEO.
Use a formal register so review happens on a set schedule, not only after a problem shows up. A register works best when each issue has one owner and one review cadence. Set response rules based on severity – weekly, bi-weekly, or monthly. Put escalation thresholds in place ahead of time and apply them the same way every time.
Use risk reviews, decision logs, and follow-up actions across teams
Run recurring risk reviews before and after process changes
Once feedback is routed to the right owner, it needs a review rhythm. Otherwise, the register just sits there until something goes wrong. A set cadence keeps feedback active instead of gathering dust.
Use a tiered cadence based on what’s happening:
- Weekly during rollout
- Every other week for migrations
- Monthly once things are stable
- Quarterly for low-impact items
At each review, re-score every item, check whether mitigation work is moving, and escalate anything above the agreed threshold.
Keep a decision log tied to stakeholder input
After a risk review, document the decision that came out of it and why it was made.
A risk register shows what might go wrong. A decision log shows what the team chose to do about it. That includes what was decided, who made the call, which options were turned down, and which risks were accepted instead of addressed. Without that record, team knowledge can vanish when one key person leaves.
Each entry should include the details that let someone trace the decision and act on it:
| Field | Purpose |
|---|---|
| Decision | Unique identifier for the specific process change or initiative |
| Owner | The individual accountable for execution and results |
| Rationale | The why behind the decision, including exceptions |
| Source feedback | Connection to stakeholder input or diligence findings |
| Risk score | Risk score based on probability and business consequence |
| Status | Current state: On track, At risk, or Blocked |
| Done when | Quantified evidence that shows the fix or change is complete |
| Dependencies | Other teams or processes that impact or are impacted by this decision |
When each decision links back to a specific piece of feedback, the loop gets closed. Stakeholders can see what they raised, and leadership can show what happened next. At that point, the log becomes the bridge between review and execution.
Track follow-up actions and compare results with and without formal governance
A decision doesn’t lower risk on paper alone. It lowers risk when follow-up shows the fix was finished and people are using it. Give every follow-up action one owner and one status.
At the next review cycle, reassess the risk score. If the score drops, the fix is doing its job. If it stays the same or goes up, the mitigation needs another look.
The gap between structured follow-up and ad hoc handling shows up fast in results:
| Outcome Area | Governed process | Ad hoc follow-up |
|---|---|---|
| Recurring incidents | Reduced through scored mitigation and re-score cycles | Repeat failures when fixes are not tracked |
| Ownership | Single owners and clear exit criteria | Vague ownership; initiatives often have no owner |
| Stakeholder trust | Decisions tied to input; feedback visibly acted on | Feedback disappears without response |
There’s a plain business reason to do this well. Only 23% of CEOs believe they have comprehensive information about the risks in their business, despite 92% agreeing such information is critical to success. Formal follow-up governance helps close that gap.
Stakeholder Engagement in Risk Management Decisions | Exclusive Lesson
Conclusion: A practical model for safer process change in SMEs
Process change can fail without much warning. Miss one feedback step, and you might miss the first sign that something is off. This model helps stop that by turning feedback into tracked risk actions.
Risk tends to drop when feedback moves through a clear workflow. Map stakeholders, collect feedback, score risks, review them on a set cadence, log decisions, and assign each follow-up action.
Key points to carry into the next process change
The shift is simple: build risk management into planning. As Mario Peshev, CEO and Founder, Growth Shuttle, puts it:
"Risk management belongs in planning, not just response."
Structured feedback turns input into action items tied to risk. Unstructured feedback can make it look like a team is listening when it isn’t doing much with what it hears. The gap shows up fast: are risks being scored, owned, and closed, or do they keep coming back as repeat incidents?
For smaller leadership teams, this kind of discipline is often easier to keep with outside advisory support. For CEOs leading 15–40 person teams, Growth Shuttle can help formalize feedback intake, risk registers, decision logs, and review cadences so process change runs on a repeatable system.
FAQs
How do I start a risk register?
Start with a living document that lists possible issues, names an owner, and tracks mitigation status.
Use a structured table to log each risk, its likelihood and impact on a 1–5 scale, the resulting risk score, and how often it should be reviewed. Risks above 12 usually need active mitigation. Risks above 16 should be escalated for executive or board-level visibility.
Which feedback should be escalated first?
Prioritize feedback that points to workflow bottlenecks or high-risk issues that could threaten day-to-day stability. Any risk with a score above 16 should be escalated right away for board-level visibility.
Escalate by scope as well:
- Workstream issues go to weekly check-ins
- Cross-workstream issues go to monthly operating reviews
- Thesis-level issues go to the board
How often should teams review process risks?
Teams should set a steady review rhythm based on their risk profile. A simple way to think about it: the higher the risk, the more often the team should check in.
Common cadences include:
- Weekly check-ins for day-to-day blockers
- Monthly operating reviews to track progress and adjust resources
- Quarterly reviews to make sure work still lines up with strategy and compliance needs
Standard operating procedures should also get a formal review every 6 to 12 months. And the risk register shouldn’t sit on a shelf collecting dust. It should stay active and be updated whenever conditions change, risks happen, or mitigation plans shift.